Momentic releases QA-Bench to measure how well AI agents find bugs in real apps
The public benchmark includes methodology and data on Hugging Face, with comparisons against Codex and Claude Code.
Read the source ↗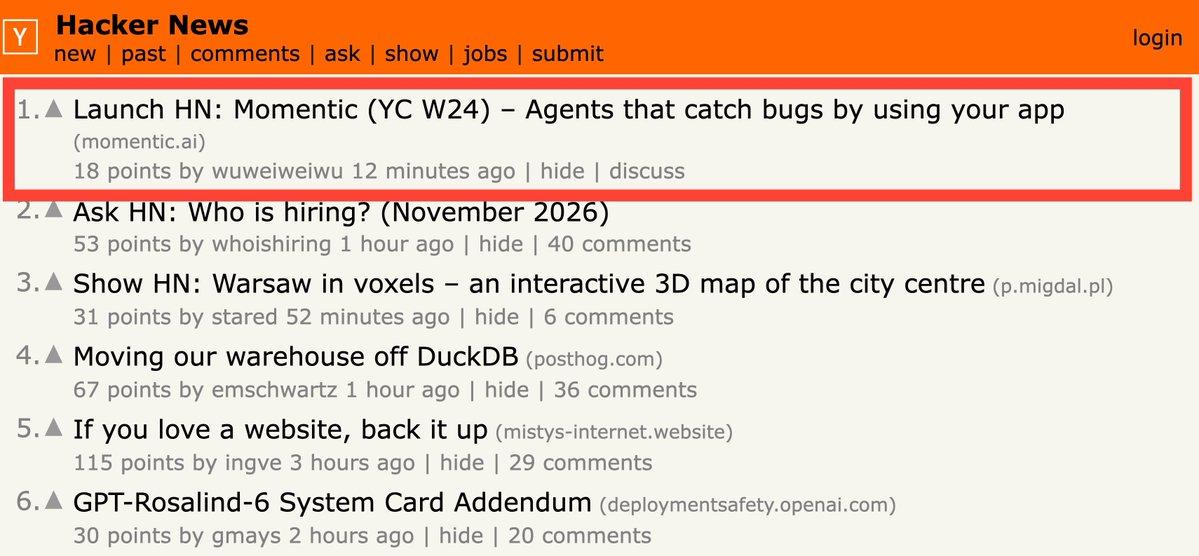
Momentic says its AI QA engineer, Mo, found 2.7× more reproducible bugs than Codex and 6.3× more than Claude Code in its own QA-Bench evaluation. The company is releasing the benchmark methodology and data on Hugging Face alongside its Hacker News launch.